GitHub’s Git storage architecture was rebuilt for a scenario that sounds made up: 5,000 agents pushing to one repository at the same time.
As of November 2026, that is not a projection. GitHub says internal testing demonstrated 5,000 concurrent agents working on a single repository, sending 7,200 pushes per second, while read traffic kept being served at consistently low latency. The company published the details, which is the part I respect most.
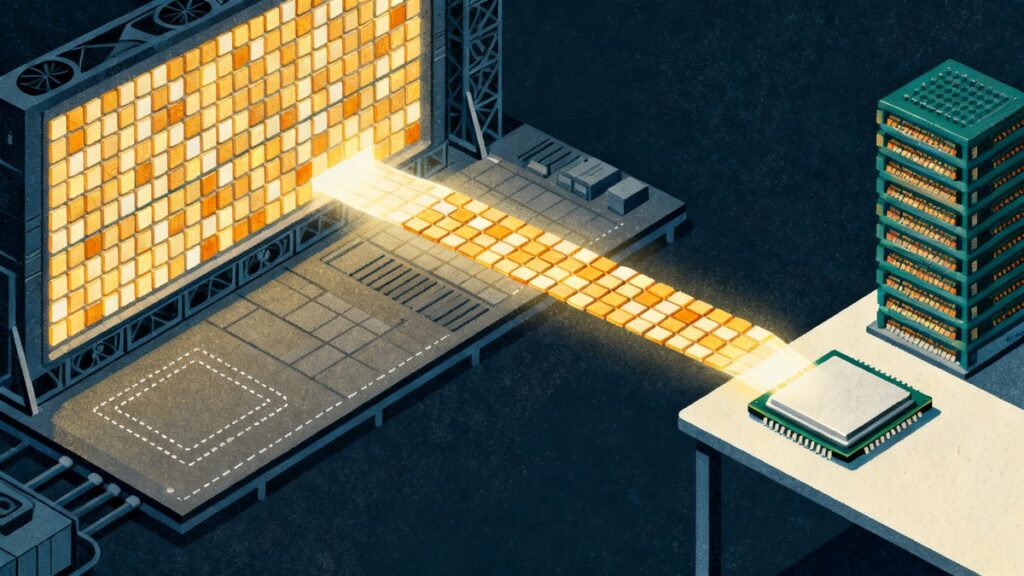
The design underneath is a storage/compute separation. Authoritative repository data lives in Azure Blob Storage. Compute workers cache data and handle requests. Object storage joins the write quorum through a component GitHub calls a virtual replica. At your terminal, nothing changes. Git stays Git. Push, fetch, branch. Same commands, same protections.
Why The Old Replicas Buckled
The previous design asked every replica to do two jobs. A comparison of the two approaches puts it plainly: GitHub’s existing durable repository replicas also supply read capacity.
Which means every replica added for reads as well adds write coordination.
Fine trade with a few humans. Terrible trade with machines pushing all day.
Picture a restaurant that requires every new waiter to co-sign every order ticket in the building. More staff, more service, and more signatures on everything before any plate moves. A repository with thirty human contributors never feels that tax. A repository where agents push around the clock pays it on every single write.
How GitHub’s New Git Storage Architecture Works
Storage/compute separation, then a per-reference write quorum. Those are the two moves.
Authoritative data lives in Azure Blob Storage.
Compute workers cache data and handle requests. And object storage becomes a full member of the write quorum through the virtual replica, backed by Azure Blob Storage.
The detail that matters more than it first appears: the write quorum is scoped to individual references. A push needs agreement only around the reference it is actually writing. Two agents pushing to two different branches never queue behind one global lock for the whole repository. So concurrency spreads across branches instead of piling up at a single door.
The kitchen comparison holds here too. The walk-in cooler is the storage layer. The cooks are compute. You hire or lose cooks without ever touching the cooler. And the cooler does not care how many cooks are on shift.
Put the two moves together and the load test reads as almost ordinary.
Reads served from cache. Writes coordinated narrowly, per reference. As of November 2026, the published figure from that test stands at 7,200 pushes per second to one repository with read traffic still at consistently low latency. The test passed. That is the flattest way to say it.
This was not a lab demo, either. GitHub says it moved a copy of 99.99999% of its repositories to Azure before the load test ever ran. Count the nines. Nobody migrates essentially the entire platform to prove a theory they are only half sure about. The bridge came first, and the 5,000-agent demonstration is what walked across it.
GitHub vs Anthropic Scion: Two Answers to Agent-Scale Git
GitHub kept the Git interface and rebuilt everything behind it. “For developers, Git stays Git,” GitHub writes.
Anthropic looked at the same pressure and made the opposite call.
It built Scion, an in-house version control system.
And says it fully migrated its monorepo from Git in five months.
Scion is a other animal end to end.
The unit of work is a “changeset,” an entry in a write-ahead log, not a Git commit. The client maintains a bounded local object cache rather than a complete copy of everything. And there is no fully materialized copy of the repository anywhere, not even on the server.
The side-by-side comparison frames the split neatly: GitHub separates storage from compute, while Anthropic moves more source-control operations onto the server.
Two bets about where the pain actually lives.
GitHub bets the Git interface survives and only the backend has to bend. Anthropic bets the interface itself is the constraint. If you are a solo operator or a small team, GitHub’s bet costs you nothing today. Because every tool, hook, and script you already run keeps working.
What GitHub’s Git Storage Architecture Means for Teams
The consequence is simpler than the architecture. The infrastructure can now absorb thousands of agents pushing at once.
Your review capacity cannot.
I run coding agents against everything I ship. The failure mode is never an agent failing to produce code. It is two agents colliding in the same file and me untangling the result afterward.
Machine contention stops being the choke point. The choke point becomes you. Your review queue, your merge conflicts, your judgment about what is safe to deploy. The repository is turning into a coordination surface for machines. And the humans left in the loop are the rate limiter.
Do you know, right now, which references your agents are allowed to push to? Most teams do not.
A short, unglamorous checklist:
– Keep pull requests small, as small diffs are the only thing review can keep up with at volume.
– Turn branch protection on and mean it, since the protections GitHub preserves only help if you have actually configured them.
– Decide explicitly which references agents may push to, so agent traffic and your deploy path never share a lane.
None of that is new advice. What is new is the urgency, since the write path just stopped being the excuse.
So do one concrete thing this week. Pick your busiest repository and audit it: who can push, what is protected, how big a typical pull request runs. And where an agent’s commit would land today. That is an afternoon of work. It is too the difference between agents as a force multiplier and agents as cleanup duty. Your next hundred collaborators will not have laptops, and the repo is where all of them will be working.
FAQ: GitHub’s Git Storage Architecture
What changed in GitHub’s Git storage architecture?
Authoritative repository data moved to Azure Blob Storage, separated from the compute workers that cache data and handle requests. Object storage joined the write quorum as a virtual replica. And that quorum is scoped to individual references rather than the whole repository.
Does Git behave differently for developers?
No. “For developers, Git stays Git,” per GitHub’s engineering post. Push, fetch, and branch work the same way as before, with the same protections in place.
What is a virtual replica?
The component that lets object storage, backed by Azure Blob Storage, act as a full member of the write quorum instead of sitting outside it as passive storage.
How many agents was this tested with?
GitHub says internal testing demonstrated 5,000 concurrent agents on a single repository, sending 7,200 pushes per second, with read traffic served at consistently low latency.
Sources
– Inside GitHub’s new Git storage architecture — GitHub Engineering
– The bridge to agent-scale Git infrastructure — GitHub Engineering
– Redesigning source control — Anthropic
– GitHub vs Anthropic Scion. Comparison guide