Hy4 Flash activates 12 billion parameters per token. The model holding them carries over 200 billion total. Every one of those weights is downloadable now, and that last fact is the one worth your attention.
Tencent announced Hy4 on November 4, 2026, describing a release it says “ranks it among the world’s leading open-source AI models.” Hy4 Flash followed as the cost-optimized sibling.
Three open-weight variants — Hy4 Flash, Hy4 Flash-FP8, and the pre-trained Hy4 Flash-base. Went up on Hugging Face, ModelScope, and GitCode. One flag before anything else: “leading open-source” is Tencent describing Tencent, on launch day. Not an outside score. That distinction runs through everything below.
Hy4 Flash Specs: 12B Active vs 220B Total Parameters
Tencent’s own repo calls Hy4 Flash “our most cost-effective Hy model to date, featuring 220B total parameters (including 64B Engram parameters) with just 12B active parameters per token.” Press coverage of the release says 224B total.
One of those numbers is wrong. Two weeks after launch, I cannot tell you which. Because the primary source and the writeups summarizing it disagree on a basic spec.
Treat both totals as provisional until someone reconciles them.
The rest of the sheet is clean. Hy4 Flash takes text and image input natively, generates text. And supports a context window of up to 1 million tokens. The backbone underneath runs 42 layers: one dense feed-forward layer and 41 mixture-of-experts layers, with identity Hyper-Connections (iHC) moving information between layers. Interesting engineering.
Zero effect on your per-token price.
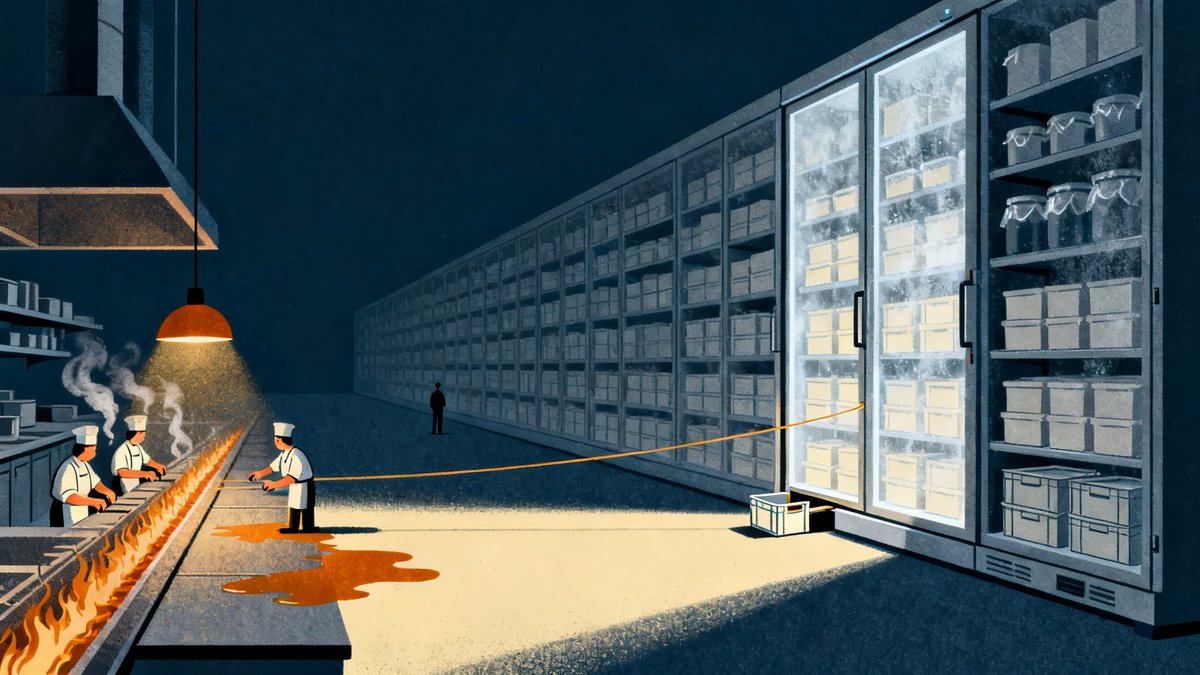
Here is the part that decides your bill. The 12 billion active parameters set your compute cost per token. The 220B total sets your memory footprint when you self-host. Think of a restaurant kitchen. Active parameters are the four cooks on the line tonight; total parameters are the walk-in fridge you keep running whether or not anyone orders. A handful of experts fire per token.
You pay to refrigerate all of it.
You hold the full weight set in memory regardless of how few experts fire. That sentence is the least dramatic one in this post and the most expensive.
| Variant | What you get | Where |
|—|—|—|
| Hy4 Flash | Full release: text and image input, text output, 1M-token context | Hugging Face, ModelScope, GitCode |
| Hy4 Flash-FP8 | Reduced-precision cut for tighter memory budgets | Same three platforms |
| Hy4 Flash-base | The pre-trained base model | Same three platforms |
Hy4 Flash License and Weights: What You Can Actually Build
Open weight means downloadable. Nothing more. The Hy4 Flash repo points to a license file. And nothing in the record I worked from lays out the terms. Honest admission: I stopped at the README rather than claiming a full read of license terms nobody handed me. The rule stands anyway. License before production, every open-weight drop, no exceptions. A download button is not a commercial-use grant.
The sequencing matters too. Hy4 landed first, live inside Tencent Cloud TokenHub, WorkBuddy, CodeBuddy, Yuanbao, WeCom’s AI Assistant (Dayuan), and ima. Positioned in Tencent’s own words as its “latest-generation large language model.” Flash was “scheduled for release soon” to “deliver greater cost-efficiency for users who prioritize high-value applications,” per the same announcement. Every major lab runs this two-step now. Hosted flagship makes the headlines. The smaller cut is the one that ends up in your own stack. Skipping the flagship announcement cost you nothing this time.
For intended use, the API documentation is more honest than the launch post. It describes hy4-flash as “a leaner, more efficient everyday workhorse, ideal for high-volume, large-scale tasks such as daily office work.” Translation: document processing, extraction, summarization, classification at volume. Not frontier reasoning. Cheap throughput — which is most of what small operations actually automate.
Hy4 Flash Benchmarks: What’s Missing
Nothing independent exists.
No third-party scores, no reproduced evaluations, no published failure cases anywhere in what I could verify. The “among the world’s leading open-source AI models” framing is a vendor describing its own product on day one. Maybe it holds up. Nobody quoting the press release knows either, and I will not pretend to.
So ignore the adjectives. Grade the model.
How to Run Hy4 Flash Locally (FP8 First)
Same sequence I run for any new open-weight release, condensed:
1. Read the license file before anything touches a paying customer.
2. Pull the Hy4 Flash-FP8 variant, since memory is the constraint that bites first on a 220B total model.
3. Route one real high-volume task through it. Long-document work is the fit, since the 1M-token context window plus 12B active parameters is the specific combination that makes it economical.
4. Keep your current model running as the control. And grade the outputs yourself, on your documents, against your quality bar.
Specs are real.
Weights are real. Reputation is unproven. That is the argument for testing it rather than believing it. And if Hy4 Flash wins on your workload, you will know it from your own numbers instead of a press release.
Hy4 Flash FAQ
What is Hy4 Flash? The cost-optimized sibling of Tencent’s Hy4 large language model. Per the repo, 220B total parameters (including 64B Engram parameters), 12B active per token, text and image input, text output. And a context window of up to 1 million tokens. Weights are downloadable on Hugging Face, ModelScope, and GitCode.
How does 12B active differ from 220B total?
Only 12 billion parameters fire per token, which sets your compute cost. Self-hosting still loads the full 220B into memory, which sets your holding cost. Cheap to run, expensive to hold.
What license applies to Hy4 Flash? The release points to a license file, but the terms are not spelled out in the verified record. Read it before any commercial use.
Where can you download Hy4 Flash? Hugging Face, ModelScope, and GitCode carry all three variants: Hy4 Flash, Hy4 Flash-FP8, and Hy4 Flash-base.
Hy4 vs Hy4 Flash — what’s the difference?
Hy4 is the flagship, hosted inside Tencent’s own products.
Hy4 Flash is the open-weight, cost-efficiency cut aimed at high-volume everyday tasks.
Sources
– Tencent announcement: Hy4 launch
– Hy4 Flash repository, GitHub
– Complete AI Training coverage of the release
– Tencent Cloud API documentation for hy4-flash