Non-Autoregressive Parallel Decoding: 10.5x Speed, One Big Catch
Non-autoregressive parallel decoding just cut decoding steps from 256 to 24 on MBPP, a 10.5× speedup reported by...
llama.cpp Can Now Compute Missed MoE Experts on the CPU
llama.cpp pull request 30966 gives the CPU an actual job in mixture-of-experts inference. When the GPU’s expert cache...
Agent-Native Primitives: What Actually Ships Your Code
Four agent-native primitives sit underneath Copilot, Claude. And Codex inside VS Code: the agent loop, the runtime that...
Persistent Memory For AI Coding Agents Just Went Mainstream
The changelog entry is almost boring. On October 28, 2026, GitHub announced that Copilot Memory is generally available...
Unslop: The Claude Skill That De-AIs Your UI
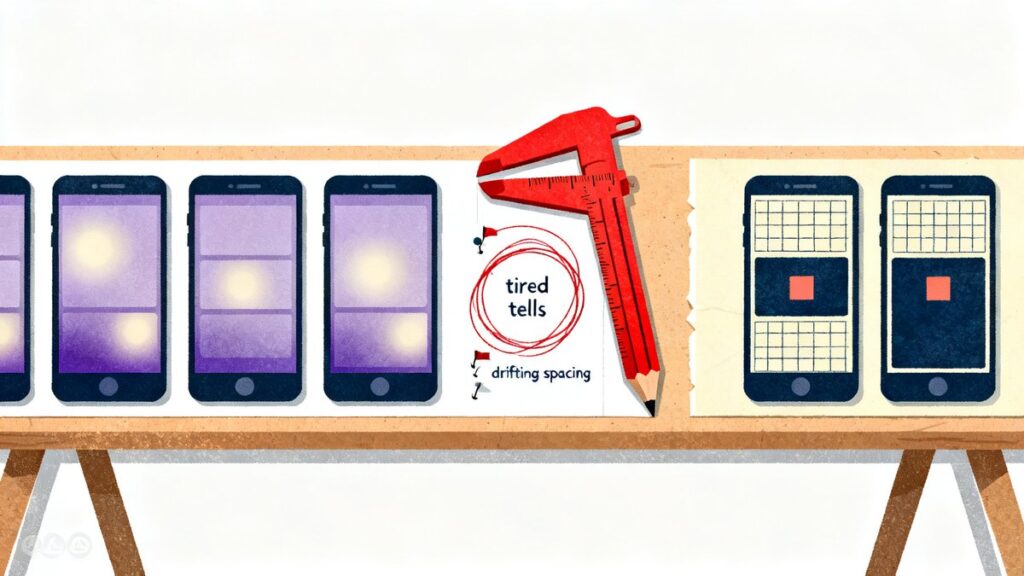
The unslop Claude skill audits five visual tells before it changes a single pixel: purple gradients, glows, emoji...
AI Agent Memory Promises 90% Token Savings. Here’s the Truth.
AI agent memory posted 91% lower p95 latency in Mem0’s own benchmark study, along with more than 90%...
Weight-Space Programming: The 0.016% Edit That Repaired Qwen
Qwen3.5-0.8B jumped from 7.9 to 48.1 percent on MATH-500 after a weight-space programming session edited 131,072 weights, roughly...
Reproducible LLM Inference Needs Fixed Batch Geometry
vLLM’s `VLLM_BATCH_INVARIANT=1` flag delivers reproducible LLM inference by making output “deterministic and independent of the batch size or...
Ripple-65B Preview: 80.52 On TerminalBench, Zero Independent Verification
Launch morning. GMI Cloud already had Ripple-65B Preview serving from its endpoints at $0.20 per million input tokens...
Kimi K3.1 Pro Open Weights Landed. Self-Hosting Can Wait.
Kimi K3.1 Pro went open-weight on November 4, 2026. Deadline day, zero slack in it. A Reddit post...